Four agents talking to one another looks impressive in a demo. It can also multiply latency, cost, and confusion without improving the deliverable. The case for multiple agents is specialization with clean accountability—not digital theater.
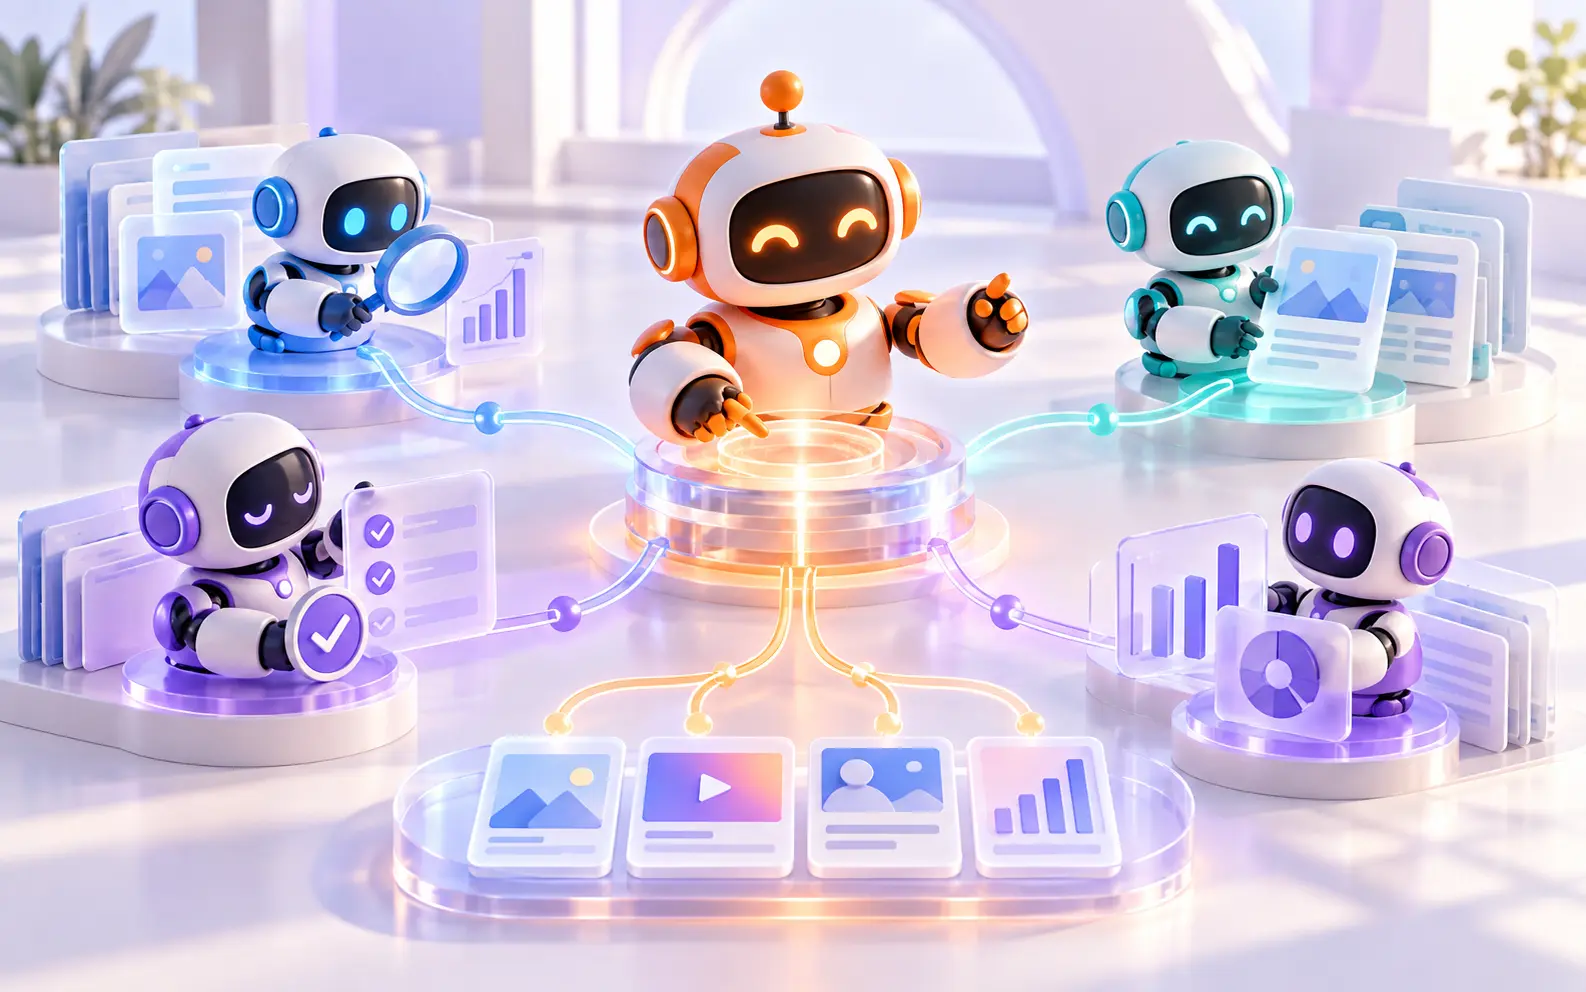
Use one orchestrator that owns the job state and delegates bounded tasks to specialists. Give each specialist a narrow input/output contract, shared evidence, separate evaluation criteria, and no authority to silently redefine the brief.
Use multiple agents only when the boundaries are real
A separate specialist is justified when it needs different tools, instructions, permissions, context, or evaluation. “Research,” “draft,” and “review” can be distinct because they behave differently. Three agents that all receive the same prompt and browse the same web are just three expensive opinions.
Different jobs
Researcher gathers evidence; creator produces; reviewer checks against a rubric.
Different volume
Parallel specialists may help when tasks are independent and latency matters.
Role-play only
“Strategist,” “genius,” and “critic” share the same access and vague goal.
A small agency architecture that stays legible
Keep shared state structured and small
Agents should hand off artifacts, not giant transcripts. A campaign job can carry: brief version, target audience, approved claims, banned claims, source pack, deliverable list, channel constraints, due date, owner, current status, and review notes. Each agent reads what it needs and returns a typed output.
A specialist may complete a task; it should not independently declare the campaign approved or sent.
An end-to-end campaign flow
- Normalize the brief.Turn the request into audience, outcome, proof, deliverables, limits, and unknowns.
- Research.Collect attributable evidence and label opinion versus fact.
- Approve direction.A human confirms message, claim boundaries, and channel plan.
- Produce.Create the required variants from the approved direction.
- Review.Check brief coverage, factual support, brand rules, platform limits, and duplication.
- Revise once.Return structured defects, not a vague “make it better” loop.
- Package.Deliver final assets and a short record of sources, assumptions, and approvals.
Prevent endless agent conversations
- Step budgetMaximum specialist calls per job.
- Revision budgetOne or two targeted cycles before human review.
- Definition of doneMachine-checkable fields plus a rubric threshold.
- Stop reasonCompleted, needs approval, missing evidence, blocked, or budget exceeded.
- No free chatSpecialists exchange structured artifacts through the orchestrator.
Evaluate specialists separately
Questions teams ask
Is a multi-agent system always better than one agent?
No. Start with one agent plus tools. Split roles only when the boundaries improve permissions, context, parallelism, or evaluation.
How should agents communicate?
Through typed, compact artifacts managed by an orchestrator—not unrestricted conversation histories.
Where should humans approve?
At strategy or claim-boundary decisions, before external publication, and whenever a specialist reports missing evidence or elevated risk.